Reasoning in Vision-Language Models
Vision-language models are good at recognising what is in an image and much less reliable at reasoning about it. We study where that reasoning breaks down, from understanding negation (knowing what is not there) to whether text-to-image models compose a scene correctly for the right reasons, and develop training and evaluation methods that close those gaps.
Publications
Right Looks, Wrong Reasons: Compositional Fidelity in Text-to-Image Generation
Proceedings of the AAAI Conference on Artificial Intelligence
·
14 Mar 2026
·
doi:10.1609/aaai.v40i46.41337
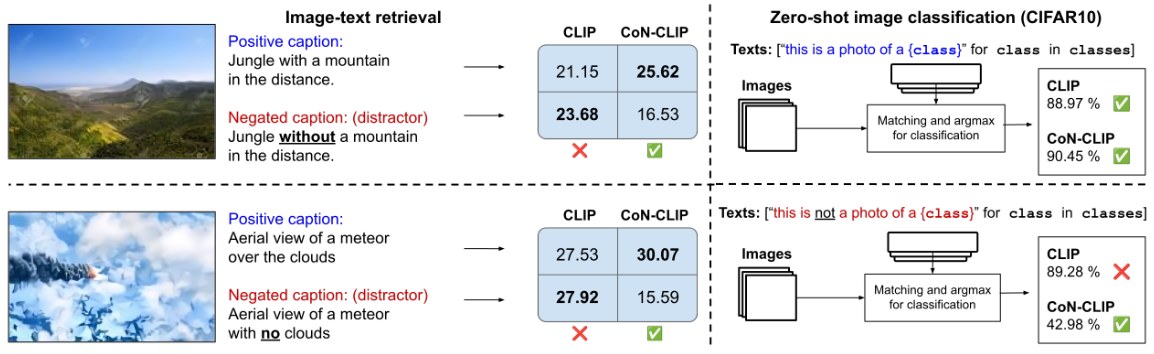
Learning the Power of “No”: Foundation Models with Negations
2025 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)
·
26 Feb 2025
·
doi:10.1109/WACV61041.2025.00777
From No to Know: Taxonomy, Challenges, and Opportunities for Negation Understanding in Multimodal Foundation Models
arXiv
·
17 Feb 2025
·
arxiv:2502.09645